ToolNova practical guide
Image OCR: 10 Practical Ways to Improve Text Recognition
No OCR engine can reliably recover characters that are not visible in the source pixels. Recognition quality therefore depends not only on the software but also on how the image is captured and prepared. The following checks are especially useful for receipts, photographed documents and screenshots.
Try it yourself: sample file and verification steps
These samples are synthetic test data created for ToolNova and contain no personal information. Records below were obtained on September 30, 2026 using the specified sources. Results cannot be generalized to other files.
 Download the sample PNG
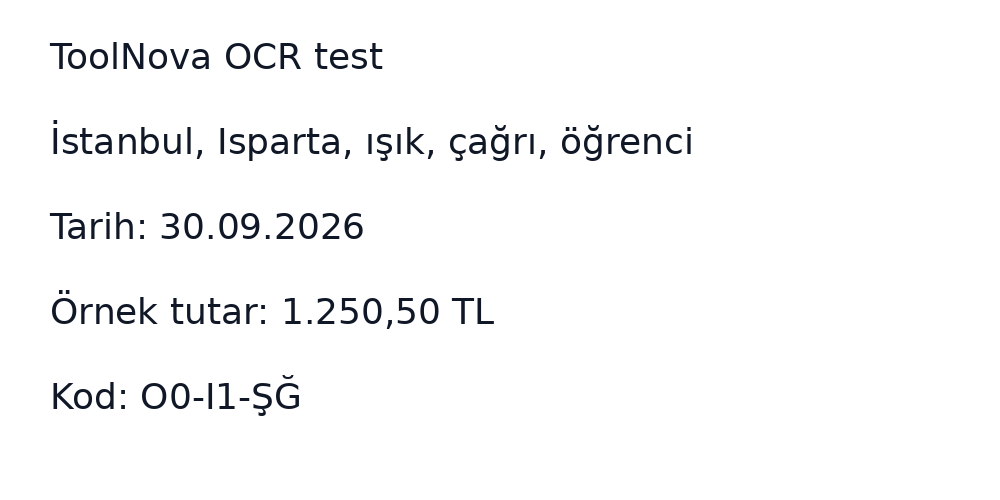
Select Turkish in Image to Text and compare the result with the source below. Check ı/İ, ş, ğ, 0/O, dates and amounts. Repeat with English and record differences; no language choice is best for every source.
ToolNova OCR test
İstanbul, Isparta, ışık, çağrı, öğrenci
Tarih: 30.09.2026
Örnek tutar: 1.250,50 TL
Kod: O0-I1-ŞĞ
Output obtained in the live test
The 1,000 × 500 pixel, 30,363-byte source PNG was processed with Turkish selected. Server-reported OCR processing time was 674 ms, excluding upload, download and network waiting. Text and Word outputs contained the same content. The date and amount were read correctly, but O/0, I/1 and Ğ/G were confused in the code. No accuracy percentage was inferred from this one sample.
ToolNova OCR test

İstanbul, Isparta, ışık, çağrı, öğrenci
Tarih: 30.09.2026

Örnek tutar: 1.250,50 TL

Kod: 00-11-ŞG
With English selected, the same source yielded “istanbul” for “İstanbul”, “Isik” for “ışık”, and “6Grenci” for “öğrenci”. Choosing the source language matters; Turkish still requires manual checks of critical codes.
This clean, single-column example does not represent handwriting, angled photos or multi-column documents. Correct errors before using the output for critical tasks.
1–3: Sharpness, resolution and cropping
Text edges need to be sharp. Motion blur and missed focus make similar characters such as “c/e,” “1/l/I” and “0/O” difficult to distinguish. When photographing a document, keep the phone steady, use enough light and move closer instead of relying on heavy digital zoom.
If the document occupies only a small part of the frame, crop away unnecessary desk, wall or background areas. Giving the OCR engine a higher proportion of real text can simplify page segmentation, but leave enough margin to avoid clipping characters at the edges.
4–6: Perspective, orientation and contrast
When the camera looks at the page from an angle, one side of the text appears smaller than the other. Perspective distortion can make reading order harder, especially in tables and multi-column layouts. Keep the camera as parallel to the page as possible and place the document on a flat surface.
Faint gray text, glare and hard shadows hide character edges. Use even lighting, remove reflective sleeves and reposition the document if flash creates hotspots. A moderate contrast adjustment can help when the source is washed out.
7–8: Language and layout expectations
When the OCR engine supports language models, selecting the right language can improve character predictions. Language-specific letters and punctuation are more likely to be recognized correctly when the engine expects them.
Do not expect a complex table to preserve every cell perfectly when using plain text OCR. Character recognition and layout reconstruction are separate problems. If the final goal is a spreadsheet, verify rows and columns after recognition.
9–10: Verify critical fields and keep the original
It may be impractical to manually verify every character in a long OCR result. At minimum, compare high-impact fields such as names, account numbers, dates, amounts, serial numbers, addresses and phone numbers against the source image. A single character error can matter in financial or administrative work.
Keep the source image alongside the corrected text. If a suspicious field appears later, you can return to the original for verification. OCR output should not automatically be treated as a replacement for the original document.
- Use sharp focus.
- Crop unnecessary background.
- Keep the camera parallel to the page.
- Reduce glare and hard shadows.
- Choose the correct OCR language.
- Verify critical fields against the original.
FAQ
Frequently asked questions
Is OCR more accurate on screenshots?
Sharp, high-contrast screenshots are often good OCR sources, though very small fonts, low scaling or complex interfaces can still cause errors.
Does enlarging a photo improve OCR?
Simple upscaling cannot recreate detail that was never captured. Acquiring a sharper, higher-quality source is usually more useful.
Can I use OCR text without verification?
That may be acceptable for low-risk drafts, but financial, legal or identity-related fields should be checked against the source.